Computational Biologist II · Broad Institute of MIT and Harvard

Computational biology.
Machine learning.
Scientific data systems.

At the Broad Institute, I lead computational development for drug-discovery screens, develop quantitative methods, and build reproducible scientific systems. I partner with experimental scientists to define analytical requirements and criteria for what advances to follow-up.

100K+small-molecule compounds analyzed
10B+compound virtual-screening pipeline
Top 1%prioritized for follow-up

Technical Expertise

Three capabilities, integrated around scientific decisions.

Computational biology, applied data science, and scientific software grounded in experimental context.

Computational Biology

Biological questions and decision context.

  • Functional genomics, CRISPRi, and perturbation screening
  • Target discovery, mechanism of action, and biomarkers
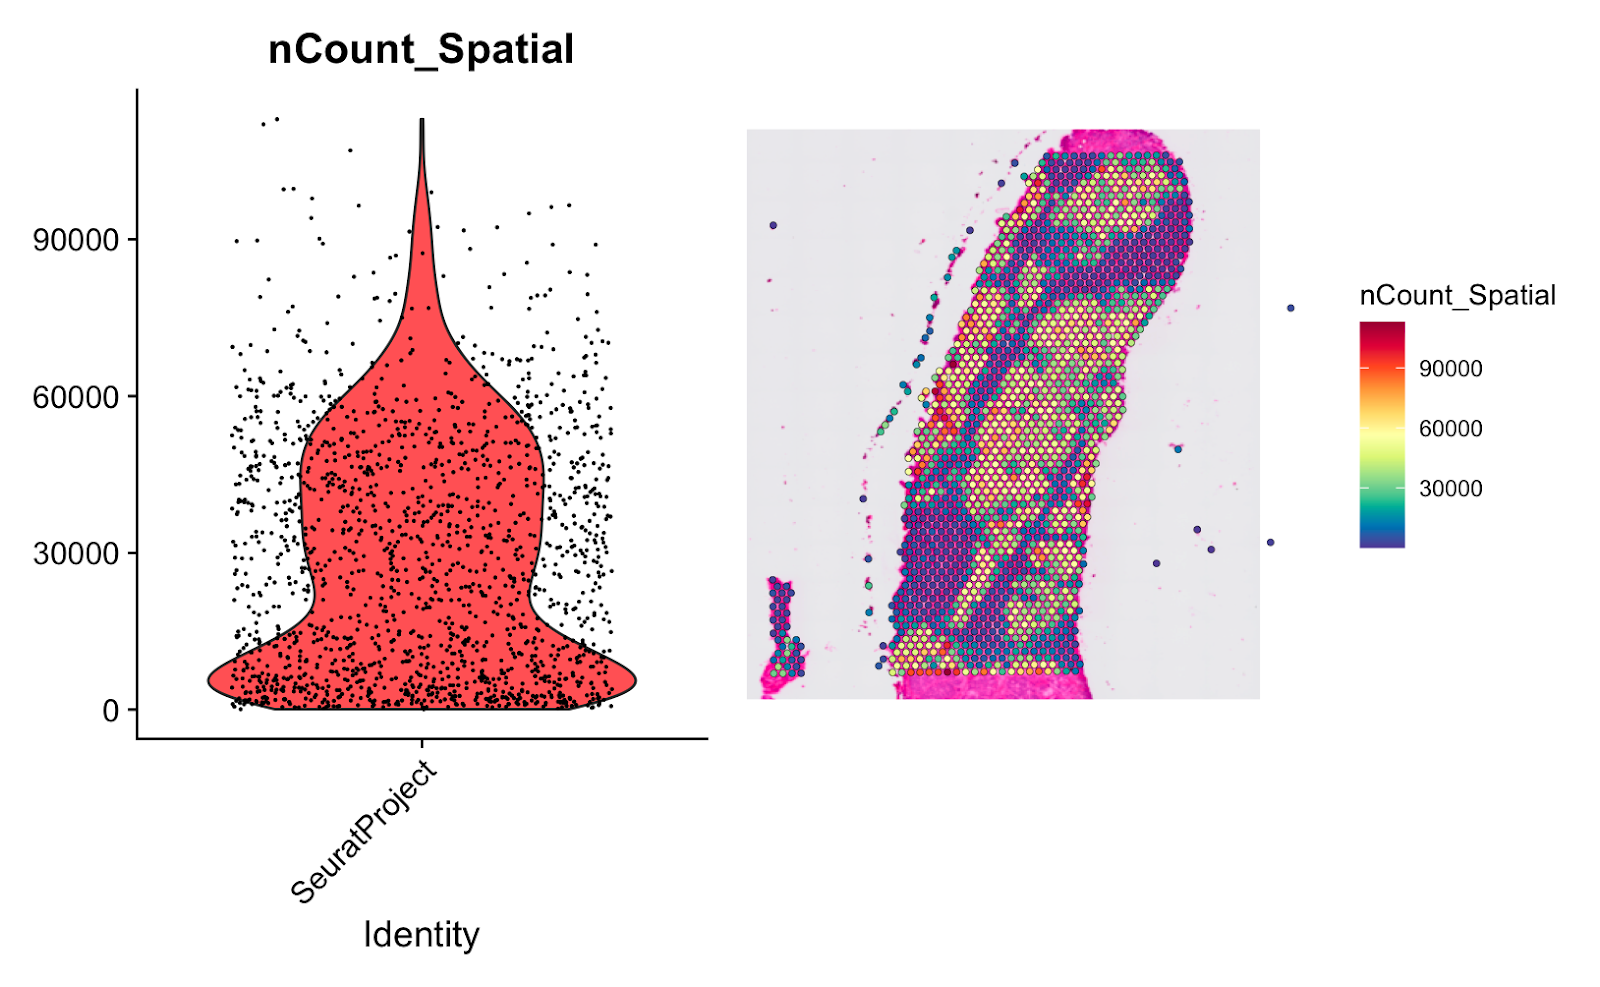
  • Multi-omics, spatial transcriptomics, and translational biology

Machine Learning & Scientific AI

Methods built and evaluated for scientific use.

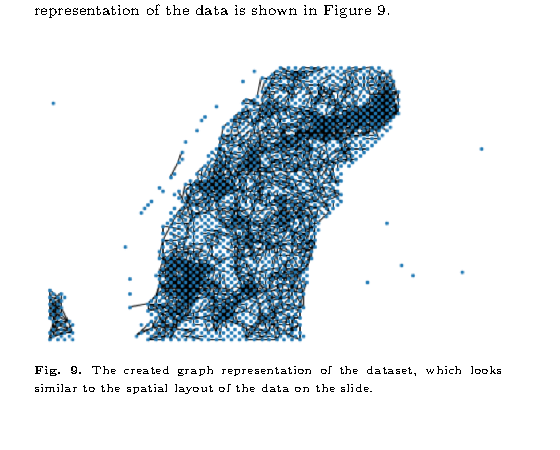
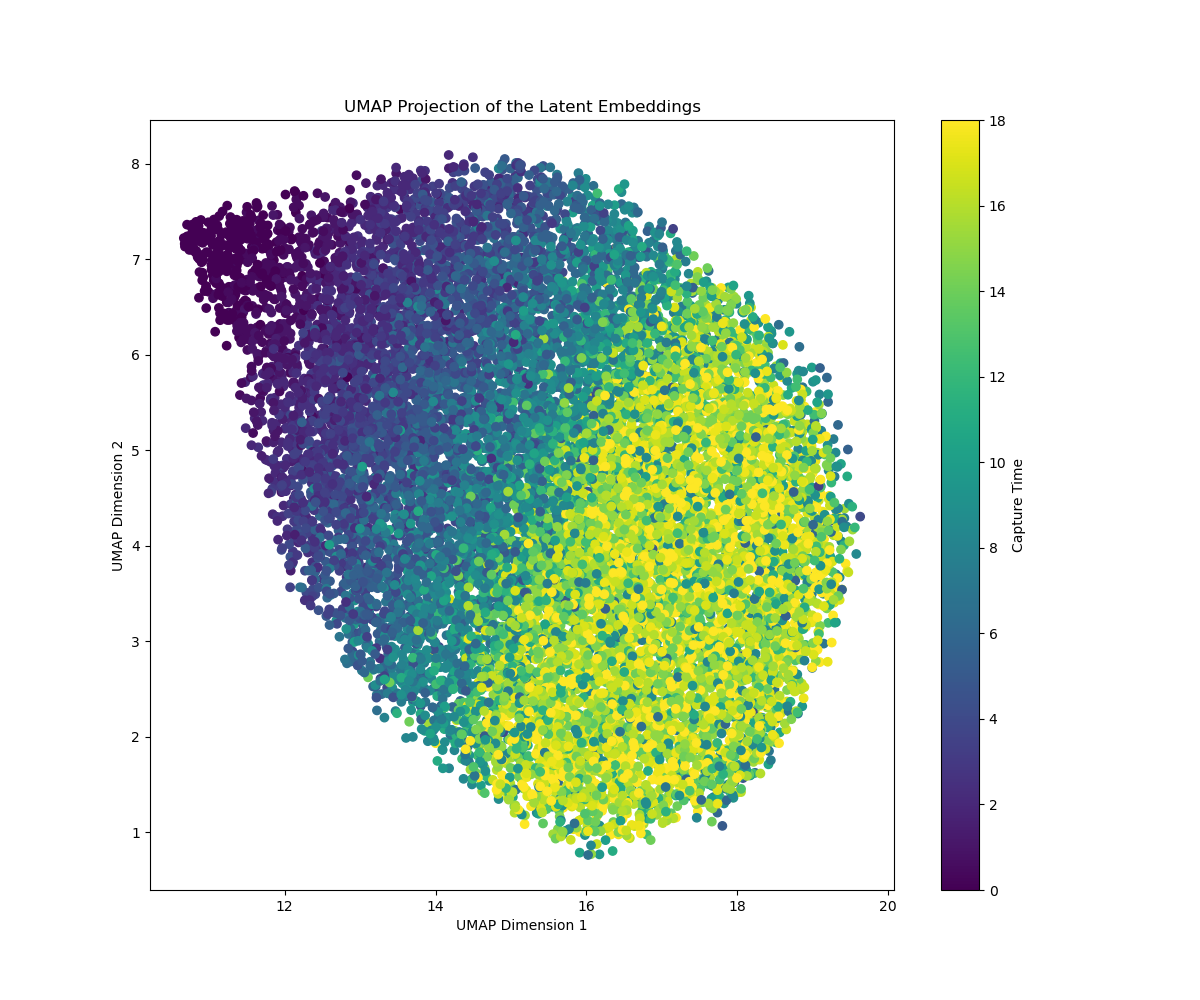
  • Representation learning, graph neural networks, and virtual screening
  • Model benchmarking and selection-algorithm evaluation
  • Knowledge graphs, RAG/LLM workflows, and agentic systems

Scientific Data Systems

Infrastructure that carries analysis into practice.

  • Python, R, SQL, APIs, and structured scientific data products
  • Workflow orchestration, containers, testing, and provenance
  • HPC and cloud computing across AWS and Azure

Translational Differentiator

Biological depth behind the computation.

MS Bioinformatics + MS Toxicology, with earlier IND-enabling PK and toxicology under GLP at Charles River. That experience informs how I assess dose, mechanism, and data integrity. Experience and training →

Additional Experience & Deeper Record

Scientific systems and evidence beyond the flagship projects.

Additional work demonstrates production-minded genomics infrastructure, while the deeper pages document research methods, public software, publications, and training.

Scientific informatics · APIs · Parallel computing

Reducing microbial-genomics turnaround with scalable data infrastructure.

I optimized API-driven retrieval, probabilistic filtering, and parallel processing across 15M+ sequences and 11+ taxa, reducing diagnostic turnaround by more than two days. The work demonstrates scientific data engineering tied directly to a biological operating need.

See the full experience →
Research · Public software · Full experience

Follow the evidence beyond the homepage.

Research details expose methods and limitations; public repositories show how I structure scientific systems; the full experience record connects that work to training and experimental context.

Connect

Building computational biology, scientific ML, or research data systems?

I am interested in computational biology, life-sciences data science, and scientific AI roles that connect quantitative methods with reliable software and experimental decisions.